 Roger Hosto
The Silent Performance Killer: How Lazy Data Types Sabotage Your Database
We have all been there. You are scaffolding a new feature, the data model is in flux, and you need to store a fast status flag or an identifier. Instead of sizing the column carefully, developers commonly misuse broad or ineffective data types like VARCHAR(MAX) or generic text fields. It is the path of least resistance—a quick way to avoid truncation errors and keep moving.
However, bypassing structured constraints or skipping over appropriate integers and UUIDs introduces silent architectural debt. While the application works perfectly in local testing, these overly broad data types bloat storage and severely degrade memory cache efficiency as your user base scales.
The Anatomy of Storage Bloat
When you define a column with an unnecessarily large capacity, the database engine often adds overhead to manage that potential variable length, or it forces the engine to push the data off-row. Even if the average string you store is only 10 characters long, relying on boundless text fields inflates the physical footprint of your tables. For example, storing a short status code in a VARCHAR(255) column instead of a CHAR(2) can use up to 10 times more space per row than necessary. In some real-world cases, switching from an oversized VARCHAR to a properly sized type has reduced overall table size by 30 to 50 percent, and improved query performance by up to 2x. At scale, this bloat translates directly into massive backups, sluggish sequential scans, and inflated cloud infrastructure bills.
Sabotaging the Memory Cache
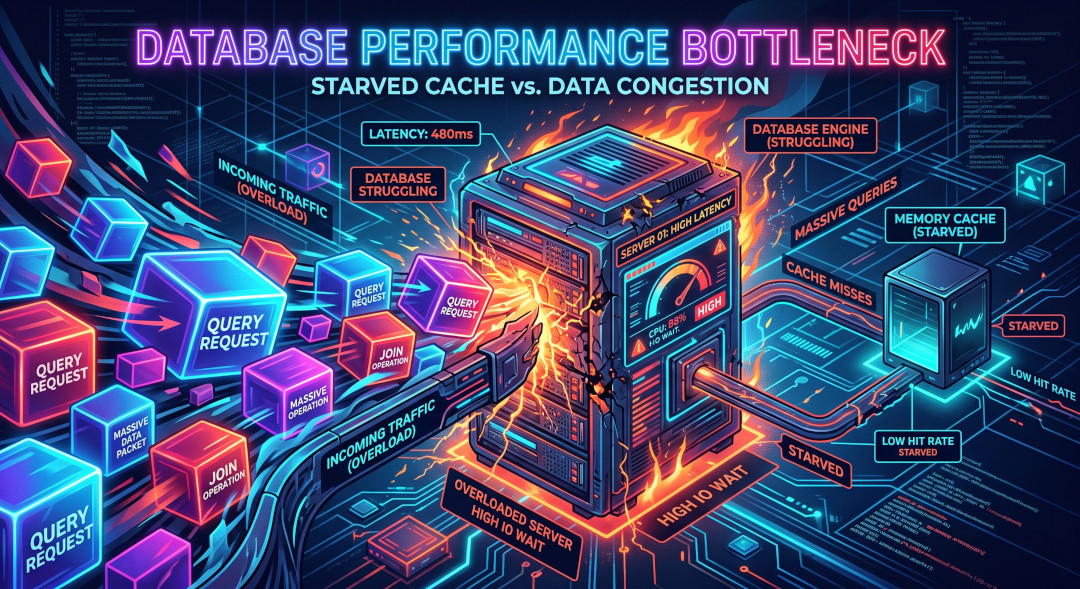
Wasted disk space is just the symptom; the real penalty hits your memory cache. Relational databases are designed to serve queries at lightning speed by holding often accessed data in RAM (memory buffers). To do this, the engine reads data from the disk in fixed-size blocks or "pages" (typically 8KB).
When inefficient, oversized data types inflate your tables, fewer rows can physically fit on a single page. Consequently, fewer rows fit into the memory cache. Instead of serving a query instantly from RAM, the database engine must constantly flush its cache and retrieve data from the much slower disk layer. You are effectively starving your system's most precious resource just to accommodate unnecessarily wide columns.
The Fix: Right-Sizing Your Schema
Stopping this performance drain needs intentional, mathematically sound schema design before deploying to production.
- Audit for defaults: Stop defaulting to generic text fields. Evaluate the business requirements and the maximum length of the data you store.
- Utilize precise, native types: Switch to appropriate integers or native UUIDs for identifiers rather than storing them as strings.
- Enforce boundaries: Apply structured constraints at the database level to ensure data integrity and reduce storage footprint.
Taking the extra minute to choose the exact data type your application requires is one of the highest-leverage performance optimizations you can make. Your database's memory cache and your on-call engineering team will thank you. To make this process easier, consider using tools that automate schema auditing and flag inefficient or risky data types. Tools like pgMustard for PostgreSQL or SQL Server's Data Discovery and Classification can quickly surface columns that aren't sized appropriately. Integrating these checks into your workflow helps ensure that your schema grows in a healthy, efficient way as your application evolves.